A machine learning model built in a data scientist’s notebook looks full of promise. For most organizations, though, that promise fades in the gap between prototype and production. This is the “AI valley of death,” where over 85% of projects fail to deliver their intended business value and stay stuck in experimentation. Better algorithms rarely fix this. A better process does.
MLOps (Machine Learning Operations) is the discipline that supplies that process. It combines the experimental nature of machine learning with the rigor of modern software engineering and DevOps. With it, AI stops being an isolated research function and becomes a scalable, reliable part of the business.
This guide lays out a blueprint for implementing MLOps best practices. It covers how to build a strong foundation, automate a complex lifecycle, and build a culture of collaboration, so your AI initiatives keep working and deliver measurable, long-term impact. Doing well with AI takes a forward-looking approach, and a solid MLOps framework is a cornerstone of any effective, future-proof AI business strategy.
Table of Contents
Open Table of Contents
- Understanding MLOps: Beyond Development to Production
- Establishing a Robust MLOps Foundation
- Data and Model Versioning Strategies
- Automating ML Pipelines: CI/CD for AI
- Monitoring and Observability for ML Models
- Ensuring Model Governance and Compliance
- Building an MLOps-Ready Team and Culture
- Common MLOps Challenges and Solutions
- Choosing the Right MLOps Tools and Platforms
- The Future of MLOps: Trends and Innovations
- Final Thoughts: MLOps as a Strategic Imperative
Understanding MLOps: Beyond Development to Production
MLOps is the operational discipline that closes the loop between creating machine learning models and putting them into live, value-creating applications. It starts from the fact that a machine learning system is more than code: it is code, data, and models that all affect one another.
Compare a master chef preparing one exquisite meal with a company building a global chain of restaurants. The chef relies on artistry and individual skill. The chain relies on standardized recipes, consistent supply chains, quality control, and repeatable processes to deliver the same experience to millions of customers.
Data science has traditionally worked like the master chef. MLOps provides the framework for building the restaurant chain.
Without MLOps, a typical workflow looks like this:
- Data scientists explore data and build a model in an isolated environment (like a Jupyter notebook).
- They “hand off” the model to software engineers as a file or piece of code.
- Engineers struggle to integrate this static artifact into a dynamic production application.
- Once deployed, the model’s performance degrades silently as real-world data changes.
- The process of updating the model is manual, slow, and error-prone.
MLOps replaces this disjointed, brittle process with a unified, automated, and continuous lifecycle that covers:
- Data management: Ingestion, validation, and versioning.
- Model development: Experiment tracking and training.
- Deployment: Packaging, validation, and release into production.
- Operations: Monitoring, logging, and governance.
- Retraining: Automating the feedback loop to update models.
With this lifecycle view, businesses can deploy models faster, reduce operational risk, and make AI initiatives reliable, scalable, and auditable from day one.
Establishing a Robust MLOps Foundation
Before you automate pipelines or deploy models, you need strategic and technical groundwork. A strong foundation means your MLOps practices are built for scale, security, and alignment with business objectives.
Defining Clear Objectives and KPIs
An ML model is only as valuable as the business problem it solves. The first step in any MLOps initiative is to translate a business objective into measurable success criteria. That means defining two sets of metrics:
- ML performance metrics: Technical measures of a model’s quality (e.g., accuracy, precision, recall, F1-score). Data scientists need them to optimize the model.
- Business KPIs (Key Performance Indicators): Measures of the model’s real-world impact (e.g., reduction in customer churn, increase in revenue per user, decrease in fraudulent transactions).
Example: For a fraud detection model:
- ML metric: Achieve an F1-score of 0.95 to balance catching fraud (recall) with avoiding false accusations (precision).
- Business KPI: Reduce fraudulent transaction losses by $1M per quarter while keeping the number of falsely blocked customer transactions below 0.1%.
Connecting these two levels ties data science work directly to value and gives you a clear basis for decisions. That link is what separates using AI for strategic business decisions from purely technical experimentation.
Infrastructure as Code for ML
Your ML systems need environments for training, testing, and serving. These environments must be consistent, reproducible, and scalable. Infrastructure as Code (IaC) is the practice of managing and provisioning infrastructure using definition files (code) instead of manual configuration.
With tools like Terraform or AWS CloudFormation, you can define your whole ML infrastructure, from virtual machines and storage buckets to networking rules, in code. The benefits are large:
- Reproducibility: You can recreate the exact environment used to train a model months later, which matters for debugging and auditing.
- Consistency: It removes “it works on my machine” problems because development, staging, and production environments are identical.
- Scalability: You can scale your infrastructure up for large training jobs and back down to save money.
- Cost control: IaC is a cornerstone of effective cloud governance and cost control, because it prevents resource sprawl and keeps computing power in efficient use.
Security Best Practices in MLOps
ML systems bring their own security challenges. Attackers may want to steal sensitive training data, poison the data to corrupt the model’s behavior, or reverse-engineer the model itself.
Build security into your MLOps lifecycle (“DevSecOps for ML”). The main practices are:
- Data security: Encrypt data at rest and in transit. Use strong access controls (IAM) so only authorized personnel and services can access training data.
- Pipeline security: Scan all code dependencies and container images for known vulnerabilities.
- Model security: Protect your trained model artifacts from unauthorized access. Put access controls on the API endpoints that serve model predictions.
- Secure infrastructure: Patch systems regularly and follow the principle of least privilege for all service accounts.
A proactive cloud security posture management strategy helps protect these complex, distributed systems from evolving threats.
Data and Model Versioning Strategies
In traditional software, git is the source of truth for code. In machine learning, three components change: code, data, and models. If you don’t version all three, your work can’t be reproduced.
Data versioning: This means tracking changes to your datasets over time. If your training data changes, your model’s behavior will change. You need to be able to answer the question: “What exact dataset was used to train version 2.1 of our churn model?” Tools like DVC (Data Version Control) work alongside git to version large data files without bloating your code repository.
Model versioning: Versioning a model means storing more than the final binary file. A complete model version should be linked to:
- The version of the training code that produced it.
- The version of the dataset it was trained on.
- The hyperparameters used during training.
- The performance metrics from its evaluation.
This gives every model in production an auditable lineage. If a model starts behaving unexpectedly, you can trace its history to see what changed and why.
Automating ML Pipelines: CI/CD for AI
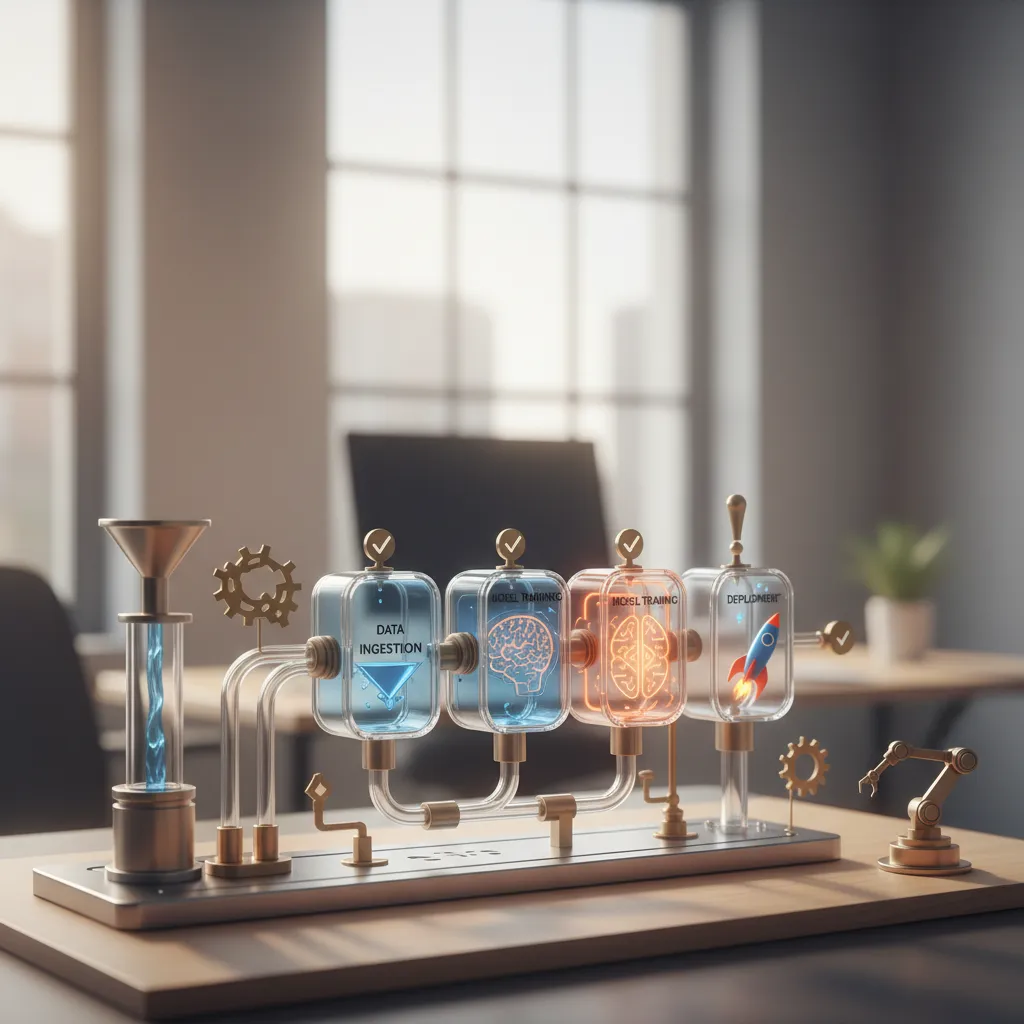
Continuous Integration (CI) and Continuous Deployment (CD) are well-understood concepts in DevOps. MLOps adapts them to the needs of machine learning. The goal is an automated, trigger-based system that can retrain, test, and deploy models with minimal human intervention.
Experiment Tracking and Reproducibility
The “CI” part of MLOps begins with experimentation. Every training job a data scientist runs is an experiment, and all experiments should be logged automatically to avoid chaos. With tools like MLflow or Weights & Biases, you should track:
- Hyperparameters used.
- Code version.
- Data version.
- Resulting evaluation metrics.
- Output model artifacts.
The result is a central, searchable registry of every experiment ever run, which supports collaboration and reproducibility.
Automated Testing for ML Models
Testing ML systems goes well beyond typical software unit tests. An automated MLOps testing suite should include:
- Data validation: Automatically checks that new data entering the pipeline conforms to the expected schema, distribution, and integrity constraints.
- Model validation: Tests the newly trained model’s performance against predefined thresholds and compares it to the currently deployed model. A new model should only become a candidate for deployment if it shows a meaningful performance improvement.
- Code quality tests: Standard unit and integration tests for the feature engineering and pipeline code.
Deployment Strategies: A/B Testing, Canary Releases
Pushing a new model to 100% of your users at once is risky. Modern MLOps pipelines use these deployment strategies to reduce that risk:
- Shadow deployment: The new model runs in parallel with the old one, receiving real traffic but not acting on it. You can compare its predictions to the current model’s without affecting users.
- Canary release: The new model is rolled out to a small percentage of users (e.g., 5%). You monitor its performance closely and, if it performs well, gradually increase the traffic share.
- A/B testing: You deploy two or more models simultaneously and serve them to different segments of your user base to compare their impact on business KPIs in a controlled experiment.
These strategies let you reduce the risk of model updates and decide with data which model performs best in the real world. This level of process maturity is part of strategic workflow automation.
Monitoring and Observability for ML Models
Deploying a model is the beginning of its life in production. Unlike traditional software, ML models can fail silently there, and their performance degrades as the real world changes. That is why continuous monitoring is arguably the most important phase of the MLOps lifecycle.
Drift Detection and Anomaly Alerts
You need to monitor for two types of “drift”:
- Data drift: The statistical properties of the input data change over time. For example, a loan approval model trained before an economic downturn will see very different applicant profiles during a recession. This drift can invalidate the patterns the model learned.
- Concept drift: The relationship between the input data and the target variable changes. For example, customer purchasing behavior (the concept) might change in response to a new competitor, even if the customer demographics (the data) stay the same.
Your monitoring system should automatically track the statistical distributions of your model’s inputs and outputs and alert you immediately when significant drift is detected. That alert is often the trigger for a new retraining cycle.
Performance Metrics and Business Impact
A comprehensive MLOps dashboard should give a real-time view of both technical and business performance.
- Operational metrics: Latency, throughput (predictions per second), and error rates of the model’s serving endpoint.
- Model performance metrics: Real-world accuracy, precision, and recall, calculated using ground-truth data as it becomes available.
- Business KPIs: The financial or operational impact of the model. For an AI-powered financial forecasting model, this would be the accuracy of its forecasts translated into dollars saved through better inventory management.
With the complete view you can judge the model’s health and show its ongoing value to the business.
Ensuring Model Governance and Compliance
As AI becomes part of more critical business processes, governance and compliance matter more. MLOps provides the technical backbone for strong governance policies.
Regulatory Compliance and Ethical AI
Regulations like GDPR (in Europe) and various industry-specific rules require that companies can explain how their automated systems make decisions. MLOps practices help you meet these requirements:
- Auditability: Versioning of data, code, and models creates a complete audit trail for every prediction. You can show exactly why a model made a specific decision at a specific point in time.
- Explainability: Add model explainability (XAI) tools, such as SHAP or LIME, to your pipelines to generate human-understandable reasons for model predictions.
- Bias detection: Build automated tests into your CI/CD pipeline to check for demographic or subgroup bias in your model’s performance, which helps ensure fairness.
Strong cloud data governance best practices are a prerequisite for building a compliant and trustworthy AI system.
Role of Human Oversight
Automation is a core principle of MLOps, but people stay responsible. For high-stakes decisions, such as in healthcare, finance, or legal applications, a “human in the loop” is essential. Your MLOps workflow should include designated points for human review and approval, such as:
- Reviewing a model’s performance and bias report before it can be deployed.
- Requiring manual sign-off for predictions that have a significant financial or personal impact.
- Periodically reviewing the overall system performance against business goals.
Building an MLOps-Ready Team and Culture
Technology and tools are only part of the picture. A successful MLOps transformation depends on people and processes, and it requires breaking down traditional organizational silos.
Cross-functional Collaboration
MLOps is a team sport. It needs one cohesive team with a shared sense of ownership over the entire ML lifecycle. This team typically includes:
- Data scientists: Focus on experimentation, modeling, and analysis.
- ML engineers: Bridge the gap between data science and engineering, focusing on building scalable training and serving pipelines.
- Data engineers: Build and maintain the data pipelines that feed the models.
- DevOps/Ops engineers: Manage the underlying infrastructure and ensure reliability.
- Business stakeholders: Define the objectives and interpret the results.
Effective AI project management helps orchestrate the efforts of this varied group and keeps projects on track.
Skill Gaps and Training
The rise of MLOps has created a need for new skills. Data scientists need to understand software engineering principles like version control, testing, and modular code. Software engineers need to understand the unique challenges of ML systems, like data drift and probabilistic outcomes. Organizations should invest in cross-training and upskilling to close these gaps. The “ML Engineer” has emerged as a role that blends expertise from both worlds.
Common MLOps Challenges and Solutions
Implementing MLOps is a journey with common roadblocks. Knowing them helps you plan ahead.
| Challenge | Solution |
|---|---|
| Technical Debt in Notebooks | Treat notebooks as a scratchpad for exploration, not production code. Enforce a process for refactoring promising notebook code into modular, version-controlled, and testable Python scripts. |
| Tool Sprawl & Complexity | Avoid adopting dozens of disparate tools. Start with a foundational platform (either open-source like Kubeflow/MLflow or a managed cloud service) and integrate other tools thoughtfully as specific needs arise. |
| Siloed Teams & Handoffs | Form cross-functional “product teams” around a specific ML application. Give the team end-to-end ownership, from data ingestion to production monitoring, to eliminate the “us vs. them” mentality. |
| Lack of Business Alignment | Start every project by defining business KPIs, not just ML metrics. Hold regular reviews with business stakeholders to demonstrate the model’s real-world impact and ensure it’s still solving the right problem. |
Choosing the Right MLOps Tools and Platforms
The MLOps tool market is large and changes quickly. The right choice depends on your team’s skills, budget, and existing tech stack.
Open-source vs. Commercial Platforms
- Open-source (e.g., Kubeflow, MLflow, DVC):
- Pros: Highly flexible, customizable, avoids vendor lock-in.
- Cons: Requires significant engineering effort to set up, integrate, and maintain. Higher operational overhead.
- Commercial platforms (e.g., Google Vertex AI, Amazon SageMaker, Azure ML, Databricks):
- Pros: Fully managed, tightly integrated components, faster time-to-market, enterprise support.
- Cons: Can lead to vendor lock-in, may be less flexible, can become expensive without proper cost management.
If you adopt commercial platforms, an effective SaaS spend management strategy helps keep costs in line with the value delivered.
Cloud-agnostic MLOps
Organizations with a multi-cloud strategy may find a cloud-agnostic approach appealing. It uses open-source tools or third-party platforms that can be deployed across any cloud provider. This increases flexibility and prevents vendor lock-in, but it often means less integration with a specific cloud’s native services (like IAM and storage).
The Future of MLOps: Trends and Innovations
MLOps keeps evolving as new challenges appear. Trends to watch include:
- LLMOps & GenAI Ops: Large language models (LLMs) and generative AI add new MLOps challenges, including prompt engineering and versioning, managing massive model sizes, and implementing guardrails for responsible AI use.
- Feature stores: Centralized platforms for storing, sharing, and managing curated features for model training and serving, which promote consistency and reuse across teams.
- Edge AI and federated learning: Deploying and managing models on resource-constrained edge devices (like smartphones and IoT sensors) is a growing area. Federated learning, which trains models on decentralized data without moving it, adds operational complexity.
Final Thoughts: MLOps as a Strategic Imperative
Adopting MLOps changes how your organization builds and manages artificial intelligence, and it takes more than a one-time technical project. It is the engine that turns the potential of data science into real-world business value.
With a solid foundation, automation, and a culture of collaboration and continuous improvement, you can move past endless experimentation. You can build a reliable, scalable “AI factory” that consistently delivers intelligent applications, lowers the risk of your AI investments, and creates a durable competitive advantage. The journey requires commitment, and the payoff is turning AI from a cost center into a core driver of business growth.